Sunday, July 27, 2014

After the fact - a new role for function points?

Just the other day I was chatting with a friend about the place of function points in software development.

While they are traditionally used as an approach to estimate the effort required to build a system, from my point of view this role has changed with the current prevalence of lean and agile methods.

Using function points to estimate effort in new project work

... is (IMHO) a difficult feat because there would be a serious amount of functional decomposition necessary which in turn would require extensive analysis which in itself would be a serious step towards BDUF. Furthermore it would require so much effort that a separate project would be necessary to get the funding for the work.

And this approach is neither very agile nor very lean. It does not address the knowledge gain – both about what the project is about and on how to go about the solution – during the project.

Making work between projects comparable with function points

... on the other hand seems quite feasible to me. Usually, after we have finished the work (and of course in an agile environment we have finished, really finished, at least some work after the first iteration) we do have measurable building blocks that can easily be measured and counted (in functionpoints).

Using function points to plan big projects

... is not such a good idea from my point of view. (Even when it is considered viable because epics seem too hard to plan with planning poker)
In my opinion using function point analyses for up-front planning is almost dangerous – for the aforementioned reasons of extensive up-front work (and implicitly commitment to solutions).
If estimating epics seems too hard there might be other reasons involved that would still be valid if function point analysis would be used. But with the kind of up-front analysis that often seems appropriate for function point analysis these points might become hidden behind too much detail. The problem with planning poker is of course that the "consensus amongst expert" that has been derived from wideband delphi depends on a certain level of detail and upon a sufficient number of available experts from the different areas of expertise.

In the end, all that planning poker does is condensing the formal approach of wideband delphi into a seemingly more informal approach based on verbal communication. Establishing a basis for estimation and installing a cross-functional group of experts is still necessary! Even if the process that can take weeks in wideband delphi is condensed to a relatively short interactive meeting. Such a group could – in a software development setting – consist of e.g. marketing, software-architects, database engineers, ux-specialists, testers, quality assurance, technical writers, and so on

If the requirements can‘t be estimated well enough, that problem is often rooted in too little experience in the domain, or missing decomposition into manageable – and understandable – units, for example stories on the next (more concrete) level of abstraction.
While function point analysis also enforces the decomposition of the requirements, it tends to drive the analysis towards a mindset of "What can be counted in function point analysis?" instead of a mindset of "What is a capability of the system that can actually be leveraged by an end-user and that I can estimate?" Therefore there is a genuine risk of trying to operate in the solution space before even the problem space has been explored well enough.

So, instead of opting for function point analysis when epics seem un-estimatable, I would rather suggest to break the epics down in such a form that a solid comparison with things that have been done before is possible. One approach to do this might be to at least name the stories on the next less abstract level. And additionally walk through a couple of user journeys.

Using planning poker to plan small increments of existing software

... on the other hand is a surprisingly good idea in my book.

The questions that have to be answered to get to the function point revolve around things like:

  • How many (already existing!) screens have to be modified and how complex are they?
  • How many tables are involved?
    (The data model and its physical representation usually also exist with existing, running software)
  • How many interface have to be touched? Are they inbound or outbound?
    Remember: The system is running already, so the interfaces are either already in place or an explicit part of the requirement.
  • How many functional blocks of what complexity are affected?

All of these issues are cleanly cut when adding small, well-defined requirements to an already existing system and thus can be counted quite easily. When implementing completely new epics, trying to put numbers to these issues requires at least the creation (a.k.a. design) of a conceptual data model and a functional decomposition of the requirements – things you would rather like to do during the discovery of the system, during and alongside the implementation.

My conclusion:
Function points can be really ugly critters – but used to the right ends they can be a tremendously efficient means.

'til next time
  Michael Mahlberg

Sunday, July 13, 2014

Testing: How to get the data into the system

Even though the correct term for a lot of the “testing” going on would be verification let‘s just stick with “testing” in the titles for the time being...

General verification workflow

The general way to verify that a piece of software does what it is meant to do seems quite simple:

  • Formulate the desired outcome for a defined series of actions
  • Put the system in a known state (or the sub-system or the “unit” – depending on your testing goal)
  • Execute the aforementioned defined actions
  • Verify that that the desired outcome is actually achieved
  • [Optional] Clean up the systems [1]

While this process sounds simple enough, there are enough pitfalls hidden in these few steps to have spawned a whole industry and produce dozens of books.

In this post I want to tackle a very specific aspect – the part where the system is put into a “known state”.

Putting the system into a known state might involve several – more or less complex – actions. Nowadays, where it's possible to automate and orchestrate the whole creation and setup of machines with tools like vagrant and puppet it is even possible to set up the whole environment programmatically.

You might not want to that for each unit test, which brings us to the question of when to setup what wich I will try to address in some future post.

The problem with the data

However big or small the test-setup is, one thing that is very hard to avoid is providing data.

The state of the system (including data) if often called a fixture and having those fixtures – known states of the system with reliable, known data – is a fundamental prerequisite for any kind of serious testing - may it be manually or automated.

For any system of significant size if there are no fixtures, there is no way to tell if the system behaves as desired.

Getting the data into the system: Some options

In general there are three ways to get the data into the system

  • Save a known state of the data and import it into the system before the tests are run.
    In this scenario the important question is “which part of the data do I load at which time“ because the tests might of course interfere with each other and probably mess up the data – especially if they fail. Consider using this approach only in conjunction with proper setups before each test, amended by assertions and backed up by “on the fly” data-generation where necessary.
  • Create the data on the fly via the means of the system.
    Typically for acceptance tests this means UI-interaction – probably not the way you want to go if you have to run hundreds of tests. Consider implementing an interface, that can be accessed programmatically from outside the system, that uses the same internal mechanisms for data creation as the rest of the software.
  • Create the data on the fly directly (via the datastore layer).
    This approach has the tempting property that it can be extremely fast and can be implementing without designing the system under test specifically for testability. The huge problem with this approach is that it duplicates knowledge (or assumptions) about the systems internal structures and concepts – a thing that we usually try to avoid. Consider just not using this approach!

So, do you actually have fixtures? And how do you get to your data?

’til next time
  Michael Mahlberg


[1]

(One can either put the effort in after the test or in the setup of the test - or split the effort between the two places, but the effort to make sure that the system is in the correct state always has to go into the setup. Cleaning up after the test can help a lot in terms of performance and ramp-up time, but it can not serve a substitute for a thorough setup.

Friday, July 04, 2014

How to get to the value(s)?

Values! That's what the Agile Manifesto – and hence the whole agile software development movement – is all about! Or is it?

Waterfall

Do you know how Waterfall first came into life? There are many stories, but a lot of them start with an article by Dr. Winston W. Royce, presented at the 1970 WESCON.

There the classical waterfall approach is lined out on the first few sentences and pictures.

And for many a reader that was enough!

And so they missed, that he continued by stating, that while he believed in the principal idea [of doing analysis and design prior to programming] he thought the implementation to be „risky and inviting failure“. He used the remainder of the paper to line out a more iterative approach, which he recommended to his readers. If only they had read thus far...

So the straw man, that Royce set up just to knock him down, has become the foundation for the waterfall model as we know it, because (some? most?) people didn't bother reading far enough.

Same in agile

The funny thing I see nowadays is that the same starts to happen with the agile manifesto.

In a lot of conversations the agile manifesto seems to have been reduced to the underlying values. Which are handily presented on the first page of the manifesto. It is funny how the room falls silent very often when I start to ask about the second page of the manifesto with the principles...

Seems like a lot of people don't look further than the first page.

How to get the values across

To me, the fact that there is (way) more to agile than only the four value statements has always been a relief – after all, up until now, nobody has found a way to install values into someones brain directly. At least not to my knowledge.

From what I understood from the behavioral psychologists, with whom I talked about the matter, the accepted way to transport values is to let the target audience experience the values through practices.

Children learn about values from the way other people act – not by what others say is right. (Claiming “Chocolate is bad for you” while munching away on a mousse au chocolat usually doesn't work to well with children.)

And – as Uncle Bob pointed out – we also infer the values a culture holds high from the behavior we can observe in that culture.

A culture in this case can be as local as a single software development team.

Thus, when everybody on the team claims “We believe in high quality software” but they cut corners every time they have to deliver, one might infer that they don't really see value in high quality software. (Which would be a pity, since – in my opinion – Quick and Dirty is very non-Agile!)

Or, when the whole team claims to love tests but none get ever written, one might infer that "testing" is in fact not really in their value set.

The opposite is not quite as simple – if we observe a team that consistently writes test we would probably infer that they hold testing high, while in fact they might just be scared by their QA department.

Nonetheless, as long as there is no way to ‘inject’ values directly, just following the practices for a while still seems to be a very good way to get at least closer to the values.

While I have seen many a project fail where every member could quote all the values from the Agile Manifesto I have not yet seen a project that adhered to all the principles and still failed.

Although I have to admit that it is a lot harder to actually follow the concrete principles than to quote the values.

Try giving the second page of the Agile Manifesto a chance – it might be worth it!

‘til next time
  
Michael Mahlberg

Sunday, June 15, 2014

The conceptual Pyramid of Agile

Sometimes it helps to organize the different concepts that are common in lean and agile methods by the relationships amongst each other – kind of like in Maslows pyramid of needs

How to introduce a mindset

There is a discussion going on between different fractions in the lean and agile continuum about “the right way” to introduce new processes and mindsets. While one approach argues to start with the values, personally I’m more inclined to start with the practices (the same for Toyota btw, at least according to their European CIO and VP)

At least for some kinds of change-management it makes sense to view lean and agile approaches in a context like this:
Let’s have a look at the layers in this pyramid from the bottom up.

Techniques

The foundation is built from the concrete techniques that are necessary to get the job done. This starts by simply knowing the syntax and semantics of the programming languages used and continues with specific techniques for analysis, design, implementation. Test Driven Development has it's place in this realm as well as continuous integration, automatic builds and build-servers (not the same as continuous integration by any stretch of the imagination), pair-programming etc.

Process

Once you know how to wield a hammer and how to handle a screwdriver – and know the difference between the two –, you still need a bigger plan to build things of real complexity. That is where process comes into play. The same applies in the world of software development. Processes lay out how different steps of work are connected to each other, who’s talking to whom and about what etc.

Process Control

But then again process alone is just the beginning - a means to an end. As one manufacturer of tires once claimed "power is nothing without control."
While processes give a good indication on how to proceed from gathering requirements through to delivering tangible capabilities to end-users they usually say little on how to control the process itself. How to identify weak points, how to coordinate the work between different stations in the process and so on. This is where process control and process improvement come into play.

Examples for the more prominent approaches

XP - foundation for a lot of things


From what I see today in the agile space most techniques which are considered to be part of "common sense" or simple "agile techniques" actually stem from the original description of eXtreme Programming (XP). Test Driven Development, Continuous Integration, Pair Programming, Standup Meetings, On-Site Customers, Sustainable Pace, Simple Design, YAGNI, Planning Game etc. all where first made public via the XP-Website and even more so through the book eXtreme Programming explained (first edition!).

Consequently when I put eXtreme Programming in the pyramid it covers quite a lot of ground. It's the only lean and agile approach that I am aware of, that covers so many topics on the techniques level. And it still does a very decent job on the process level. It even has some very clear points on process control.

Scrum - Widely applicable, and not really software specific

At the time of this writing Scrum has a subjective market share of 92.6% and it appears that almost everybody who is not really part of the ‘inner circles’ of the lean and agile community assumes that Scrum and Agile are ‘almost synonyms.’ Of course nowadays many people claim that Scrum requires unit-testing, continuous integration, user stories and so forth. But if you look it up in the Scrum Guide you'll find nothing like that mentioned - after all it’s only 16 pages anyway. 16 important pages without question, but they don’t tell you how to implement Scrum.
And that’s by intent.
Scrum is like a template that you can and should build upon - but you have to flesh out the detailed workings all by yourself. And they are much more complex than the usual picture that fits on the back of a coaster. (I wrote about this in German a while back - even if you don’t speak the language I think the pictures give a good overview of the differences)

When I try to put Scrum in the Pyramid I end up with a very well defined approach to the topic „process“ – with some very small extensions into process control and techniques.

The Kanban Method - getting control


The Kanban Method for knowledge workers is an approach defined by David Anderson based on the way Toyota optimizes their processes.

While some people see Kanban as a different approach to software development – saying things like “we switched from Scrum to Kanban”. David Anderson himself points out that this is not the case, since The Kanban Method is “just” a way to run the process – what ever your process may be. You can (and should IMHO) even run Scrum using Kanban for process-control.

When placing The Kanban Method into the pyramid it fits nicely into the upper triangle, called “Process Control”, and has just a small, well defined extension into the “Process” layer.

Start with the foundation

A short while ago Uncle Bob wrote a very nice blogpost on ‘The True Corruption of Agile’ and argued in a similar direction - the practices form the culture and the culture is identified by the practices present. So, following this pyramid and Uncle Bob’s point of view, I think it is a good idea to make sure to have the foundation (the practices) intact and use all the concepts on the appropriate level of abstraction.

Where do you try to make changes happen?

’till next time
  Michael Mahlberg

P.S.: I introduced the German version of this pyramid as part of a (German) [podcast episode back in 2012][za-episode], as part of Maik Pfingsten’s Zukunftsarchitekten Podcast.

Monday, June 02, 2014

"The Sky's the Limit" ?

Limit the Work in Progress

That's the second of the core practices in the Kanban Method.

But is the Work in Progress really the only thing that should be limited?

Features in production can be unlimited - or shouldn't they?

Lot's of boards i have seen have unlimited "In Production" columns - or even feature an infinity sign (∞) above it.
Although I can relate to the Idea of having an infinite amount of room for features and capabilities that the world could use.

But then again there is a flip side to that coin...

When you have a product, you've got to support it!

In project work people – and yes, I have to admit, I'm one of them – tend to focus on the deadline – after all one definition of the term project is that it is a "... planned set of interrelated tasks to be executed over a fixed period ..." (emphasis added), so naturally this fixed time scope has an impact on our decisions – as it should.

But when we think in terms of products this focus has to shift. We have to think beyond the delivery date. All of a sudden all those features are potential entry points for additional feature requests, bug reports, support demands, documentation demand and all other kinds of work-generation.

So at least on the portfolio level I think, it is a good idea to make sure that you don't end up with too many things in production.

So, unless you're doing it already, what do you think about putting a limit on the Features in Production?

till next time
  Michael Mahlberg

P.S.: Of course the number of bug-fixes in production is only limited by the number of bugs we put in the system - and since we have the chance to put new bugs into it every time we change one tiny little thing, that column (bugs-fixed) really should have a ∞ on it...
Same goes for the typical UHD (user help desk) tickets - even if it has a certain charm to limit the number of times a user may call after he killed his system, that kind of limit doesn't seem really feasible to me.
I'm really talking about product features at the portfolio level here.
And of course, as usual, YMMV

Sunday, May 18, 2014

Testing in Production?? Of Course! No Never! … ?!?

Recently I’ve come across a number of discussion on testing in production and whether this is good or bad.

Misunderstandings all the way down

Of course it all depends on your perception of what “testing in production” means. If it means delivering products that ripen at the client (what is called “Banana Software” in Germany) that’s quite different from when it means “being able to probe the running system without (too much) disturbance of vital funtions”

How do other professions handle it?

A little while ago I elaborated a bit more on the subject of testing and I also think most of the ideas from this earlier article are still valid. Testing should contribute to better, and more reliable solutions. Whether this requires testing at creation time, build time, roll-out time or during production, testing at the right level with the right approaches is a great thing – of course!!

What do you think?

’till next time
  Michael

Sunday, May 04, 2014

The blackout version of “stop-the-line”

As the story goes:

“Whenever a worker in that Toyota plant saw anything suspicious or a fault in the product he worked on, he pulled a cord hanging from the ceiling and the whole production line stopped.”

This may seem counterintuitive at first, but actually makes a lot of sense if the circumstances are right. Consider for example a misalignment between rear view mirror and type label on the bonnet of the car, that is discovered close the end of the production line. If it is just caused by a misplaced label, stopping the line might be ‘a bit’ over the top, but if it is caused by misaligned mounting holes for the bonnet (drilled at the very beginning) which in turn leads to errors everywhere downstream from that station (bent hinges, torn padding, sheared bolts etc.) it might be a good idea to stop the line as early as possible and fix the root cause first.

But that’s not related to software, or is it?

This might seem to be less of a problem in software, but from my experience it isn‘t – quite the contrary. Let‘s just assume that a new function is introduced in the newest version of a library or framework and this operation is redundant (to an existing version) and also faulty. Not “stopping the line” and eradicating the problem at it‘s roots will probably lead to a widespread usage of exactly that new function. Sometimes in fact so widespread that the whole system becomes unstable – and a maintenance nightmare as well!

But how to do it in (software-related) development?

Most development teams with a “stop-the-line” policy tend to use another concept from the TPS, the andon, a system to spread important information by visualizing it excessively. A common example for this is a traffic light or a set of lava lamps.
But there is a problem with these approaches – they still require everyone to follow the agreement, that a faulty build means “stop-the-line”. Also they only work for faulty builds – not for conceptual problems.

A really cool (but slightly scary) version – The Blackout! …

… was recently brought up by a client of mine: connect the “stop-the-line”-Buzzers (or cords) with a dedicated power circuit for the displays… Thus effectively once someone hits the “stop-the-line”-Button all screens go dark!
Even though this idea came up as a somewhat humorous remark, I could imagine that this might actually work – at least for teams that have reached the high quality levels typical for ‘hyper-productive’ teams.

So – what’s your policy for defects? And what’s it going to be?

’till next time
  Michael Mahlberg

Sunday, April 20, 2014

Remember: to backlog (verb) means ‘to pile up’…

And the noun means

“2. an accumulation of tasks unperformed []…“ – Merriam-Webster online dictionary

Translating the word to German makes it even worse: According to dict.cc amongst the German translations there are:

  • Rückstand (lag, deficit, handicap)
  • Nachhohbedarf (a need to catch up)

So clearly there are some negative connotation with regard to the term backlog. Still it has become a term with positive connotations in the software development community within less than two decades.

Yet –regardless of the positive connotations–, time and time again I see backlogs used in a way that seems counterproductive to me, Accumulating more and more “undone work” in the “backlog” - whether it is called backlog or feature-list or ticket-store or any other name.

In these cases, the items in that list really become a “Rückstand” as we would say in Germany - a lag with a need to catch up!

Of course there are several countermeasures to this – Backlog Grooming probably being the best known. But lean approaches also point to another idea on how to handle this: be very well aware of what your backlog really is and what you commit to!

Backlog vs. Ready-Column

Little’s law tells us that the average time an item spends in the system is determined by the work in progress divided by the time it takes to work on one item.


If we trust in this formula, basic mathematics tell us that if we put infinity in the numerator the result will also be infinite.

Thus, if we don’t put a limit on our backlog, we do not have a predictable time to completion.

Let‘s draw a picture of that:

Very often task-boards, scrum-boards, informal kanban-boards etc. are organized like this:


An unlimited input column (in Scrum for example it is the product-owner‘s job to keep the backlog prioritized the right way, resulting in an ample amount of preselected work for the next iteration), followed by some columns for the different stations in the process and finally an unlimited column for the finished work. While one might argue about the last one – which would make a good topic for a post on it‘s own – in general there is nothing wrong with this setup.

The problem arises when people forget that they can‘t make predictions about the whole board. Since the first column is endless (i.e. not limited) the average time any item spends in the system implicitly also goes towards infinity.

Now for the simple solution:

Only promise what you can control!


Without changing even one stroke on your board, just by communicating clearly that the predictability begins where the control begins, a significant change in expectation management might occur.

(Of course this was originally part of most agile approaches - it just happens that nowadays it seems to be forgotten from time to time…)

Shifting to an input queue

While we‘re at it: Why not change the wording to reflect the difference? While a _‘backlog’_ is a – potentially endless – list of things ‘not yet done‘ what we really want to talk about is a list of thing ‘to be done in a foreseeable, defined future‘. For me, one term that captures this concept nicely is the _‘input queue’_ – a term frequently in use in the lean community. And while I‘ve seen many (product-) backlogs without a limit, I have not yet come across an input-queue without a limit.

’till next time
  Michael Mahlberg

Sunday, April 06, 2014

Some models don’t need to show off…

Bubbles don’t crash – or so they say.

As most of us know, this doesn’t apply to stock-market bubbles. Or housing bubbles. This adage – “Bubbles don’t crash” – is targeted to a kind of bubble that’s specific to the software world.

The argument that “bubbles don’t crash” refers to the ‘bubbles’ that sometimes are used when modeling system behavior – be it informally on a white-board of in a tool. It’s just another way of asking the wiscy-question: Why Isn’t Somebody Coding Yet. Both adages show quite clearly that not everybody sees a huge value in extensive modeling.

Even though my own enthusiasm for modeling everything has some very clear boundaries I do advocate building (visual) models as a means of communication, as a way to verify assumptions and for whole lot of other reasons. (And please use a standardized notation and put legends on everything that goes beyond that notation if you want to use at some point in the future. Like: in an hour from the moment you create it.)

So, yes, I do think that it’s a good idea to stop drawing pictures at some point and start putting things in more concrete representations, but what I don’t understand is why some people shy away from everything that is called a model with a rendition of ”Bubbles don’t crash“ on their lips.

The majority of models we encounter are much more than only a picture – the formula p * v = const for example is a model of the behavior of gas under pressure. It means that with twice as much pressure an ideal gas will have half the volume. This is called the “Boyle–Mariotte law” and one of the first models every Scuba diver has to learn. Because it also means that with half the pressure the volume will be twice as much. Which can have serious consequences if the gas is the air in your lungs and you are not aware of this model.

Of course in reality this model is not the way the gas behaves – there are numerous other factors (like the temperature for example) that also have an impact, but for the purpose of the context the model is good enough – and not graphic at all.

And there are a lot more models like this. The so-called velocity in Scrum is one for example. Just to get back to software development. And so is Little’s law, famed in the Kanban community.

Another “model” that we come across very often is the []state-machine]state_machine - known to some from petri-nets to others from the bare theory of information system and yet to others from the UML-state diagram. A lot of ‘cybernetics’ is actually done by state-machines and in many programming environments modeling behavior through state-machines is so ubiquitous that we don‘t even notice it any more. Actually every time someone implements the ‘state’ pattern from the Gang of four pattern book they build of model of desired behavior – even though they do not implement a state-machine (but that would be a topic for another post).

And even if it is not about programming, but about the process around it – building a model is quite helpful and makes it possible to verify your assumptions. You think you can complete twice as many features with twice as many people? The model for that could be features_completed = number_of_team_members * time. And that model can be verified very easily. (Or – as I would predict in this case, according to Fred Brooks‘ seminal book The Mythical Man Month: falsified…)

So, from my point of view, embracing models and the idea of modeling is quite helpful – even if most models are not visible.

’till next time
  Michael

Sunday, March 23, 2014

In Kanban the kanban is not the kanban - What?!?

In Kanban the kanban is not the kanban - What?!?

In the early stages of the introduction of Kanban systems many organizations struggle with the implementation of the pull signal and how the cards represent the pull signal.
In my experience a lot of this confusion is caused by semantic diffusion and the fact that “The Kanban Method” (for software development and other knowledge-work) often gets over-simplified and is reduced to a lax translation of the word kanban and the original 3 rules for a Kanban (capital K) system.

Basics

Let’s look a bit deeper into this
As David Anderson points out in his famous blue book the word kanban means (more or less) «signal card» and such a card is used to visualize a so called pull request in a traditional kanban environment.

Now there is a lot of information put into one little sentence. What is a traditional kanban system anyway? What is a pull request? And what’s different in our Kanban (capital K) systems?

A “traditional” kanban system is the kind of kanban system that has been in use at the production plants of Toyota and the like to optimize the flow of physical work products through the factory. Here the upstream station – that is, any station that lies before another station in the value stream – gives out kanbans which represent their capacity. These kanbans act as tokens for the downstream stations to request new material – or, to pull the material.

But what is different in “our” Kanban systems? Well, the reaon for the capital K is the fact that we’re working with a different kind of representation in “The Kanban Method” (for software development and other knowledge-work). On page 13 of the aforementioned book David points out that

«… these cards do not actually function as signals to pull more work. Instead, they represent work items. Hence the term ‘virtual’» (emphasis mine)

Virtual pull signals

So what about the pull signal in this scenario? Isn’t it all about establishing a pull system? Well, it’s covered in work. Literally. Almost. But at least it can be covered by work as the following illustration shows.

A very simple board

A kanban board in use

Some work moved

A kanban board in use

More work moved

A kanban board in use
As you can see: you can’t see any pull signal - only the work.

That’s because the pull-signal is actually hidden behind the work and not really visible. At least not in this rendition. It is possible to make it visible, but only for very simple boards. All that’s needed here is a little annotation.

A very simple board with annotation

A kanban board annotated with pull signals
A kanban board annotated with pull signals…

Board filled with work

An annotated board in use step-1
The same Kanban board in use – all the pull signals hidden by the work. Looks quite similar to the non-annotated board, doesn’t it?

Some work moved into production

An annotated board in use step-2
So now, when the cards are moved, the pull-requests become real visual signs.

Work getting pulled all over the board

An annotated board in use step-3
And when the pull-request are fulfilled, that in turn reveals more pull requests and so on.

A more complex board

Actually most evolved Kanban board contain at least some queue-colums - often differentiating between “doing” and “done.” Now the annotation approach doesn’t work any more because the pull signal becomes completely virtual.

Let’s have a look at this as well.

The same work on a more elaborate board

Board with explicit “done” columns
Work in progess shows up in the doing colums of course

Some work is done

Board with explicit “done“ columns after some work is done
Even though some cards are moved around, no WIP-Limits are broken and no pull request issued (WIP-Limits in this example go accros doing and done)

Invisible pull signal

A pull signal is implied but not visible yet
Now that a work-item has left its WIP-boundaries a pull request is implied - but not at all visible.

Virtual pull request

The pull signal in Numbers
In fact the pull-request is only ‘visible’ by comparing the actual Work-In-Progress – in this case 2 – with the WIP-Limit, which is (3) in this example. Hence the pull request can be calculated but is not visible to the naked eye. Which fits in nicely with the notion of a “virtually signalled pull request”. This can be translated to “virtual kanban”. And of course virtual kanbans live on ”virtual kanban boards” in “virtual kanban systems”.

’till next time
  Michael

Sunday, March 09, 2014

Don't be too SMART - Goals, Targets and Lighthouses

The idea of SMART goals has such appeal to many people, that they try to put everything in these terms. And I have to admit that I'm a big fan of the SMART concept myself.

Having goals that are:

  • S pecific
  • M easurable
  • A ctionable
  • R ealistic
  • T imed

is very helpful when I try to decide whether to start a certain task or not. Whenever I hold an operations review or a retrospective I remind people to think about the SMART acronym whenever they they refer to actions.

As an example from the software development world “We should clean up our code” is not a very SMART goal if you look at it. “We want to reduce the function size of every function to less than twenty five lines by applying ‘extract method’ until next month” may not speak very well to the non-initiated, but it surely is SMART.

Sometimes I may overshoot in this quest for clarity. Not all goals have to be perfectly SMART. Especially with long term goals it is sometimes a good idea to aim for a “goal” that is not really reachable but that can show the way nonetheless. Some goals are targets that you want to hit, for some goals you want to pass between the goalposts (or over the finish-line for that matter).

Some goals really should be treated more like lighthouses by fishermen. You want to move towards them when it's appropriate but you can never reach them and probably don't even know their specifics – but they still help you find your way. (Besides: when your in a seagoing vessel and do reach them bad things happen, but that may be pushing the analogy to far)

So the picture in my mind has changed over the years and nowadays I try to use the SMART concept whenever I deem it appropriate, but I also try to find enough lighthouses on the way.

TTFN
   Michael

Sunday, February 23, 2014

Blocked by multitasking

Blocked by multitasking!

Teams who struggle with delivering software seem to share one common characteristic that has turned out to be a recurring theme in my consulting work - the tendency to multitask.

As I mentioned earlier it is very easy for a team to be busy all the time – even so much that they might be on the verge of a breakdown – while a lot of the work products go stale because they sit around idling for extended periods of time.

Chris Matts and Olav Maassen do a wonderful job of debunking the myth of «effective multitasking» in their graphic Novel Commitment. When they talk about hidden queues they explicitly mention that multitasking is just that - a queue of things unfinished. In fact, at least from my experience, the queues created by multitasking with the best of intentions (I can't finish task A so I'll just start on task B until I can work on task A again so that I don't have to idle an burn precious development time) are much worse than defined queues in the process because they tend to be barely visible. On one hand these concealed queues hide the fact that Task A is blocked. On the other hand the have to be managed in the back of the head which adds to the cognitive burden of the person working on the task(s). This more often than not this leads to “I can't finish task L so I'll just start to work on task M... oh, wait task D seems to be workable ... hmm but so is task H ... ”.

So, if you want to do yourself and you colleagues a favor, please apply the hackneyed but true optimization rule to multitasking: "Don't do it" ... or switch to the advanced Version of that rule "Don't do it – yet".

Make blockers – which would drive you to multitask – explicit and squelch them as soon as possible. And visualize any kind of queue you start to create, so that you and others can manage it.

'til the next time
  Michael

Sunday, February 09, 2014

Let's Scale the Small Team Approach?!?

After the chaos report came out in the mid nineties and made the public statement that 53% of evaluated projects where "challenged" and only 16% of them could be considered "successful" a lot of people started to focus on the errors that supposedly had been made in the 53% of challenged projects. And from the tries to eradicate those errors from all future projects a lot of the so called ”heavy“ processes where born. For the curious: the remaining 31% of projects got cancelled before they ever saw the light of day.

Yet some people focused on the question what the 16% of successful projects did differently – in line with the old coaching mantra of "catch them doing something right." Amongst other things a lot of these projects followed what today would be called an agile approach - kind of living and breathing some of the principles behind the agile manifesto even though that didn't even exist at that time.

Although the principles could be weighed differently one of the key concepts in my perception always was

The most efficient and effective method of conveying information to and within a development team is face-to-face conversation.

which also requires the teams to be of manageable sizes – the magic number 7 ( plus or minus two ) comes to mind.

Because the number of required communication lines grows exponentially with the number of team members it quickly gets impractical to have face-to-face conversations with larger teams and this in turn contradicts the whole idea of "scaling agile."

Of course it's possible to develop software in an agile manner with more that just one team, but then something else has to come into play. At least "Agile" as defined by the agile manifesto doesn't account for scaled agile. Scrum tried to address this topic with the Scrum-of-Scrums, but I think nowadays there are more obvious ways. Like integrating agile teams via a lean organization. You might want to give it a try.

Cheers
   Michael

Sunday, January 26, 2014

Busy Products - Idle Workers

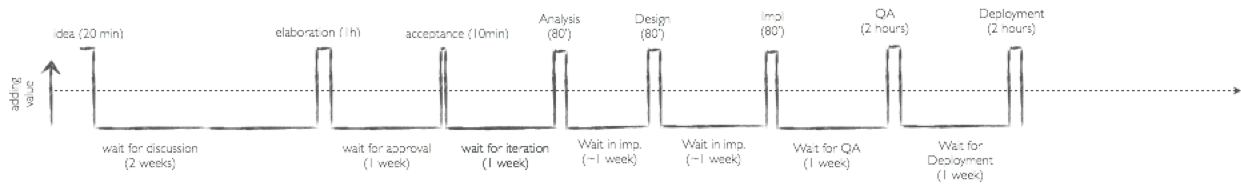
Once you start investigating workflows from the point of view of the work-items instead of from the workers perspective interesting things start to show. One tool to do this is the "value stream analysis" – one of the tools in the lean approach.

One of the fascinating things that came up again when Tom did that in a simulation at the Agile BI-Conference in December '13 was this same fact, that is often the root-cause of a certain kind of workplace unhappiness: the difference between the idle-time of the person doing the job (nearly no idle time at all) and the idle-time of the ‘item under construction’ – or product – which might easily approach or even exceed 80%.

If we take one requirement as the work item and map out its way through two weeks of development in a simple two-state graph we see that there are only small peaks of work while the work-item itself is idle most of the time.

The workers on the other hand – who try to fit as many requirements as possible in their time-box – are always in a busy state!

So, if it takes forty days to deliver a net worth of one workday it is no wonder that perceptions of workload might differ 'a bit' depending on your vantage point.

After all: however busy I may feel, as soon as I try to do five things in parallel, this also means that whenever I work on one of them, four of them must lie around idling. Totaling an average of 80% idle-time per Item. When I think about this it makes me want to introduce more measures to limit my work in progress every time!

So, have a good time mapping out the value-streams of the work-items that are most important to you – you never know what you might find out.

Cheers,
   Michael

Sunday, January 12, 2014

Not all simulations scale

I really like simulations as a way to introduce engineering practices. According to the old proverb I hear and I forget; I see and I remember; I do and I understand, there is hardly a better way to teach the concepts and mechanics of an approach than by actually living through it.

But some parts of simulations can be extremely misleading. Some things scale down very nicely other not at all. Even in physics it's not possible to really scale down everything - that's why wind-tunnels can't always be operated with normal air but need special measures to achieve a realistic environment.

But back to simulations in the field of knowledge-work...
I ran the getkanban simulation (v2) a couple of times now and found that it does a very good job of scaling down the mechanics and at the same time illustrating some of the concepts in a ver tangible manner. Except for the retrospectives or operations reviews.
With the Kanban Pizza Game the effect was even stronger. When we ran it at the Limited WIP Society Cologne(German site) we really liked the way it emphasized the tremendous effect that can come from limiting the work in progress and other aspects of the Kanban Method - except for the retrospectives.
With 5 Minutes for a retrospectives and given the fact that speedinguptheconversationdoesntreallywork (speeding up the conversation doesn't really work) it is hard to hear everyones voice in a retrospective. And of course – as Tom DeMarco points out in "The Deadline" – people also can't really speed up their thinking. It takes a certain amount of time to process information.
What's more: Scaling down retrospectives or operation reviews this much gives people who never experienced a real retrospective a wrong impression – and totally contradicts the concept of Nemawashi!

And this is true for most of the aspects that involve human interaction – root cause analysis, value stream mapping, A3-reporting, designing Kanban systems (as opposed to using them) etc. This is one of the reasons Tom and I designed the Hands-on Agile and Lean Practices workshop as a series of simulations alternating with real-time interjections of the real thing (e.g. a 30 minute value-stream mapping inside a 20 minute simulation, so that people really can experience the thought-process and necessary discussions).

Nowadays I try to balance my simulations in such a way that the systemic part of an aspect is displayed and emphasized through the simulation while the human aspects are given enough space to be a realistic version of the real thing.

What do you think?

Cheers
  Michael